





Inference Gateway
The Vaktex inference gateway is one streaming API for many AI models, built for security work. When a model refuses, the gateway detects it and finishes the request on another model. When your connection drops, the answer keeps coming and you pick it up where you left off.
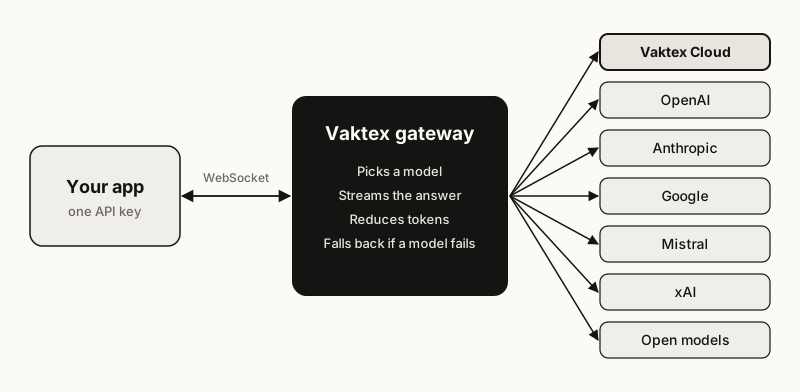
Plenty of gateways put one API in front of many models. This one is built around the problems security teams hit every day.
Refusals don’t stop the work
Security work asks models about exploits, malware and attacks, and models sometimes refuse legitimate requests. A single provider turns that into a dead end.
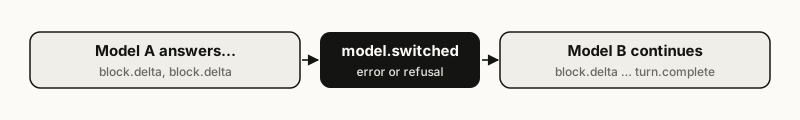
The gateway watches for refusals, whether the provider flags one or the model writes one into its answer. When it sees one, it hands the request to another capable model and continues from where the first one stopped. You get a model.switched event so you know it happened, and your stream carries on. If every model refuses, you get a clear refused error instead of silence.
Errors and outages work the same way: the turn moves to another model instead of failing.
No vendor lock-in, and no oversized models
You are not tied to one provider. Models from several providers share one request format, so switching means changing two strings.
You also do not have to use the biggest model for everything. With auto routing the gateway prefers cheaper models and moves up only when you ask for harder work, and you can pin a small model whenever you want one.
Built for long runs
Most model APIs stream over SSE, which ties the whole response to one open HTTP connection. If your network blips during a long request, the response is gone and you start again.
The gateway streams over a WebSocket instead, and every event is numbered. If your connection drops for any reason, the turn keeps running. Reconnect to the same session within five minutes, say where you stopped, and the gateway replays what you missed and carries on live. See Reconnect and resume.
And the basics
- One integration. One request format and one event stream for every model.
- One set of limits. Monthly, weekly and per-provider spend limits apply across everything you use.
- Tools stay yours. Models can ask to run tools, but the gateway never runs them. Your code decides what happens.
How it works
A turn is a request and its stream
You open a WebSocket and send a start frame holding the whole conversation. The gateway answers with a sequence of small events: the text as it is generated, then a final event that says how the turn ended and what it used.
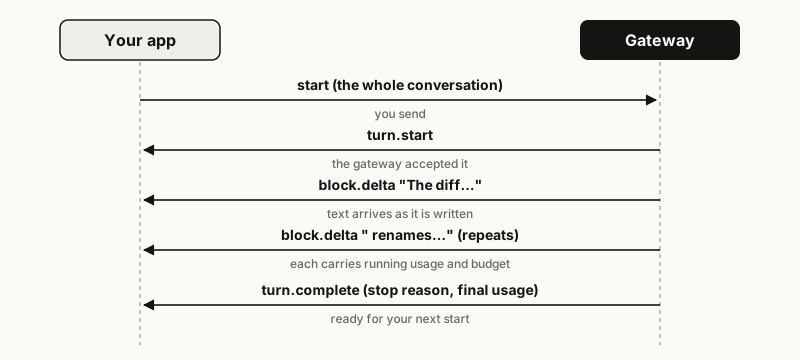
You do not have to wait for the full answer. Show each piece as it arrives.
The conversation is yours
The gateway does not remember earlier turns. You send the full message history each time, which means you control exactly what the model sees. See Conversation state.
What you can do
| Guide | What it covers |
|---|---|
| Quickstart | Get a key and run your first turn |
| Text inputs and outputs | Send messages, stream text, choose models |
| Image inputs | Ask questions about pictures |
| Structured outputs | Get JSON you can parse |
| Function calling | Let a model request your functions |
| Conversation state | Build multi-turn chats and reconnect to sessions |
| Extend the models with tools | Run a tool loop |
| Errors and handling | Error codes, stop reasons, limits and retries |
Endpoints
| Stream | wss://gateway.vaktex.com/vaktex/v1/stream |
| Reattach to a session | wss://gateway.vaktex.com/vaktex/v1/stream/<session_id> |
| Model catalog | GET https://gateway.vaktex.com/vaktex/v1/registry |
| API Docs | gateway.vaktex.com/openapi |
Good to know
Preview models. Some models in the catalog have "preview": true. They cost less, and in exchange the requests and responses of every turn sent to them are kept and used for training. The gateway only uses a preview model when you name it. It is never chosen by auto routing or as a fallback.
Data handling. The gateway erases a session’s stored events five minutes after the last connection closes and no turn is running. Where the provider supports it, the gateway asks the provider not to store requests. The catalog lists each model’s effective retention time, capped at 90 days.